Research
Research on multimodal understanding, temporal video grounding, and vision-language models.
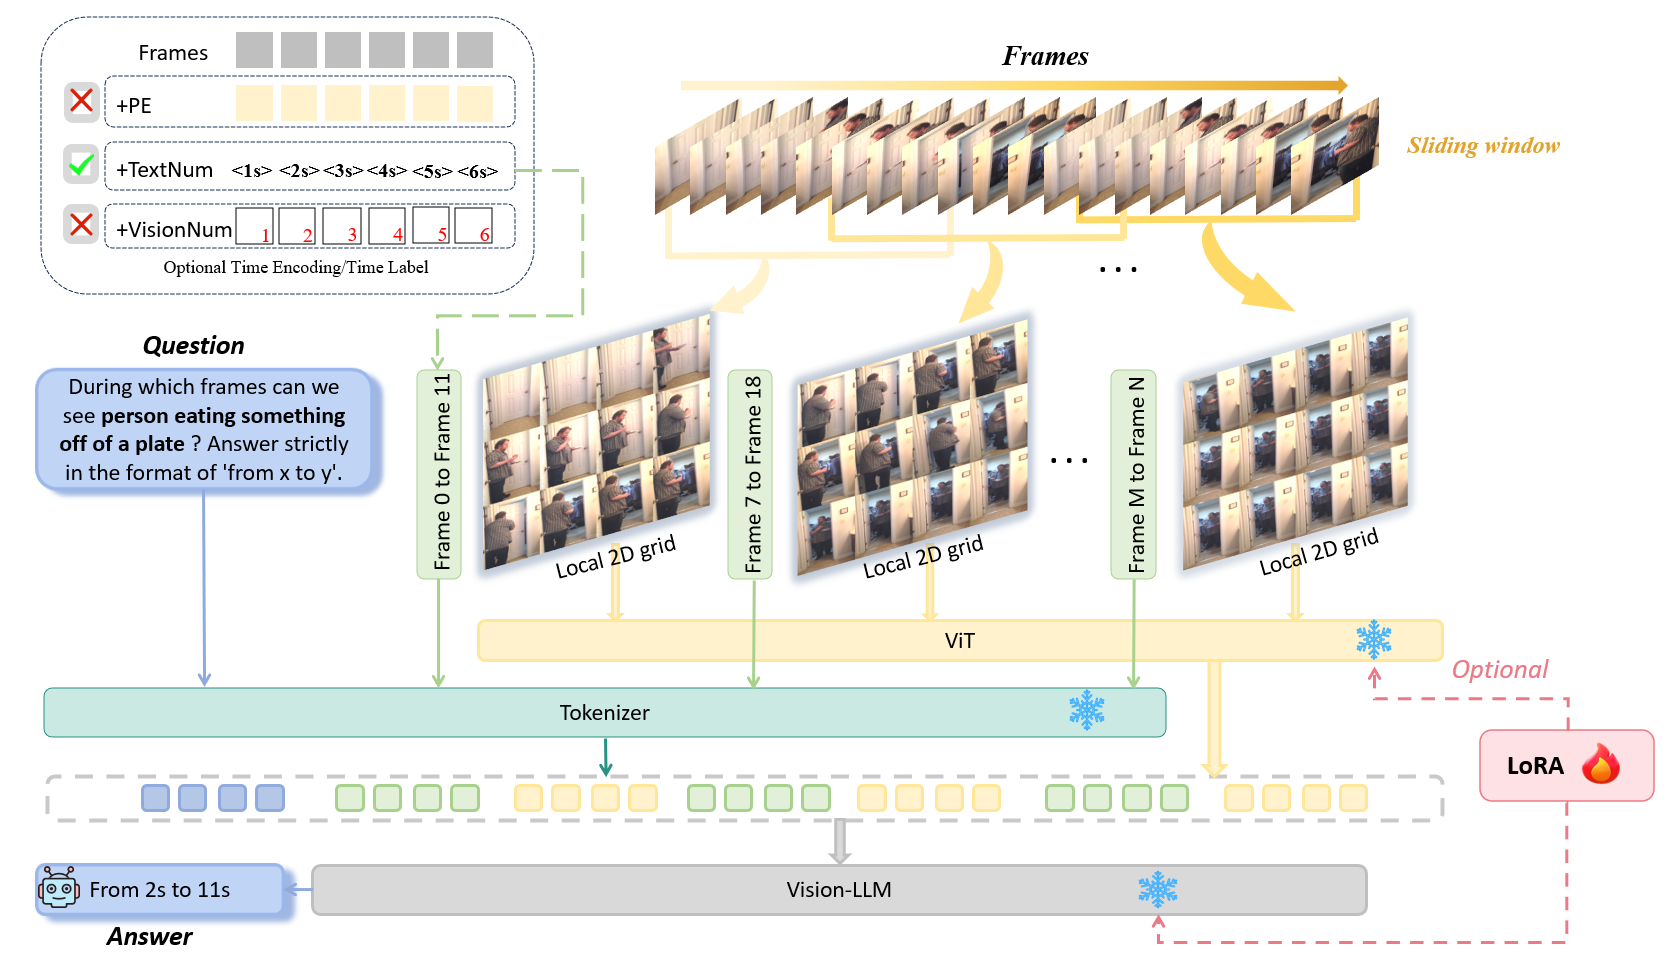
T2SGrid: Temporal-to-Spatial Gridification for Video Temporal Grounding
Chaohong Guo, Yihan He, Yongwei Nie, Fei Ma, Xuemiao Xu, Chengjiang Long
Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) 2026
A unified cross-modal video representation framework that converts local clips into spatial grids and introduces composite textual timestamps for explicit video-time alignment. The approach was evaluated across Qwen2/3-VL and LLaVA-OneVision backbones on temporal grounding and long-video understanding benchmarks.
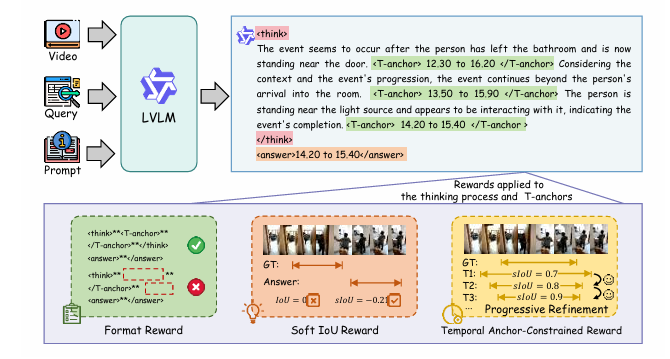
TAR: Temporal Anchor-Constrained Reasoning for Video Temporal Grounding
Chaohong Guo, Xun Mo, Yongwei Nie, Fei Ma, Xuemiao Xu, Chengjiang Long
Proceedings of the European Conference on Computer Vision (ECCV) 2026
A verifiable multimodal reasoning framework that embeds explicit temporal-anchor visual checkpoints into chain-of-thought reasoning and uses progressive rewards with GRPO. It builds a roughly 30K-example self-bootstrapped reasoning dataset and reaches 61.1 mIoU and 50.2 R1@0.7 on Charades-STA.